

Version1.2.15
Size21.7GB
Downloads12,523,521
Updated2025-03-08
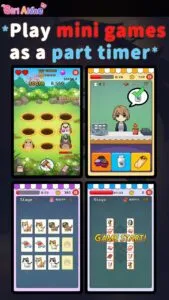
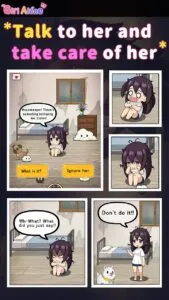
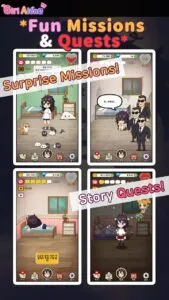
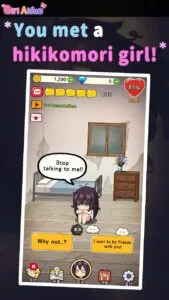
Advertisement
import logging
from selenium import webdriver
from selenium.webdriver.common.by import By
from selenium.webdriver.support.ui import WebDriverWait
from selenium.webdriver.support import expected_conditions as EC
from selenium.common.exceptions import TimeoutException
from selenium.webdriver.common.keys import Keys
from selenium.webdriver.common.action_chains import ActionChains
from openai import OpenAI
import time
import os
import requests
from PIL import Image
import re
import random
import pyperclip
from io import BytesIO
import traceback
# Konfiguracja logowania
logging.basicConfig(level=logging.INFO, format='%(asctime)s - %(levelname)s - %(message)s')
logger = logging.getLogger()
class TextModifier:
def __init__(self):
self.api_key = "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"
self.client = OpenAI(api_key=self.api_key, base_url="https://api.perplexity.ai")
self.input_path = r"C:\Users\Dawid\Desktop\skrypt gamejot\WP\SKRYPTY\DROID.COM - HIHE\arty"
def modify_text(self, input_file_path, output_file_path, title):
try:
logger.info(f"Rozpoczynanie modyfikacji tekstu dla pliku: {input_file_path}")
# Odczytanie tekstu z pliku
with open(input_file_path, 'r', encoding='utf-8') as f:
text_to_modify = f.read()
logger.info("Tekst odczytany z pliku.")
# Przygotowanie wiadomości dla API
messages = [
{
"role": "user",
"content": (
"Your task is to completely rewrite the text below into a new, unique version. "
"Requirements:\n"
"1. MOST IMPORTANT: Create entirely new sentences and paragraphs - do not copy the original text\n"
"2. Rewrite each paragraph using different words and structure\n"
"3. Keep the same meaning and tone, but express it in a completely new way\n"
"4. Add some new relevant details while maintaining the core message\n"
"5. Use synonyms and alternative phrases\n"
"6. If any heading contains 'About' followed by game name or word 'game', add 'APK' at the end\n"
"7. Break down the content into logical sections\n\n"
"STRICT FORMAT REQUIREMENTS (VERY IMPORTANT):\n"
"- Each section title MUST be wrapped in tags, like this:
w tekście
match = re.search(r'
tags, like this: Title Here
\n"
"- Each paragraph MUST be wrapped in
tags, like this:
Text here
\n" "- DO NOT use markdown headings (###, ##, #)\n" "- MUST use HTML tags, not markdown\n\n" "Example format:\n" "About Game APK
\n" "First paragraph text here.
\n" "Next Section
\n" "Next paragraph text here.
\n\n" f"Here's the text to rewrite:\n\n{text_to_modify}" ), }, ] # Wysłanie żądania do API response = self.client.chat.completions.create( model="llama-3.1-sonar-small-128k-online", messages=messages, temperature=0.8 ) # Sprawdzenie odpowiedzi z API if response and response.choices: modified_text = response.choices[0].message.content logger.info("Odpowiedź otrzymana od API:") # Log first 100 chars of the response # Znajdź pierwszy znacznik w tekście
match = re.search(r'.*?
', modified_text, re.DOTALL)
if match:
# Wytnij tekst od pierwszego do końca
cleaned_text = modified_text[match.start():]
else:
# Jeśli nie znajdzie , użyj całego tekstu
cleaned_text = modified_text
# Dodaj dodatkowe sprawdzenie, czy tekst nie jest pusty
if not cleaned_text.strip():
logger.error("Wygenerowany tekst jest pusty!")
cleaned_text = modified_text # Użyj oryginalnej odpowiedzi
# Konwersja markdown na HTML jeśli API mimo wszystko użyło markdown
lines = cleaned_text.split('\n')
converted_lines = []
for line in lines:
# Konwersja markdown nagłówków na HTML
if line.startswith('###'):
line = f"{line.replace('###', '').strip()}
"
elif line.startswith('##'):
line = f"{line.replace('##', '').strip()}
"
elif line.startswith('#'):
line = f"{line.replace('#', '').strip()}
"
# Dodaj APK do nagłówków About jeśli brakuje
if '' in line and 'About' in line and 'APK' not in line:
if 'game' in line.lower() or title.lower() in line.lower():
line = line.replace('
', ' APK
')
# Konwersja ** na
if '**' in line:
# znajdź tekst między ** i zamień na tagi strong
while '**' in line:
start = line.find('**')
end = line.find('**', start + 2)
if start != -1 and end != -1:
text = line[start+2:end]
line = line[:start] + f"{text}" + line[end+2:]
# Dodaj tagi do paragrafów jeśli brakuje
if line.strip() and not line.strip().startswith('<'):
line = f"
{line.strip()}
, użyj całego tekstu
cleaned_text = modified_text
# Dodaj dodatkowe sprawdzenie, czy tekst nie jest pusty
if not cleaned_text.strip():
logger.error("Wygenerowany tekst jest pusty!")
cleaned_text = modified_text # Użyj oryginalnej odpowiedzi
# Konwersja markdown na HTML jeśli API mimo wszystko użyło markdown
lines = cleaned_text.split('\n')
converted_lines = []
for line in lines:
# Konwersja markdown nagłówków na HTML
if line.startswith('###'):
line = f"{line.replace('###', '').strip()}
"
elif line.startswith('##'):
line = f"{line.replace('##', '').strip()}
"
elif line.startswith('#'):
line = f"{line.replace('#', '').strip()}
"
# Dodaj APK do nagłówków About jeśli brakuje
if '' in line and 'About' in line and 'APK' not in line:
if 'game' in line.lower() or title.lower() in line.lower():
line = line.replace('
', ' APK
')
# Konwersja ** na
if '**' in line:
# znajdź tekst między ** i zamień na tagi strong
while '**' in line:
start = line.find('**')
end = line.find('**', start + 2)
if start != -1 and end != -1:
text = line[start+2:end]
line = line[:start] + f"{text}" + line[end+2:]
# Dodaj tagi do paragrafów jeśli brakuje if line.strip() and not line.strip().startswith('<'): line = f"
{line.strip()}
Advertisement
"
converted_lines.append(line)
modified_text = '\n'.join(converted_lines)
# Zapisanie zmodyfikowanego tekstu do pliku
with open(output_file_path, 'w', encoding='utf-8') as f:
f.write(modified_text)
logger.info(f"Zapisano zmodyfikowany tekst do pliku: {output_file_path}")
else:
logger.error("Błąd podczas komunikacji z API.")
except Exception as e:
logger.error(f"Błąd podczas modyfikowania tekstu: {str(e)}")
def process_all_files(self):
try:
for filename in os.listdir(self.input_path):
if filename.endswith(".txt") and not filename.endswith(" AI.txt"):
title = filename.replace(".txt", "")
input_file_path = os.path.join(self.input_path, filename)
output_file_path = os.path.join(self.input_path, f"{title} AI.txt")
self.modify_text(input_file_path, output_file_path, title)
except Exception as e:
logger.error(f"Błąd podczas przetwarzania plików: {str(e)}")
class TechlokyScraper:
def __init__(self):
self.driver = webdriver.Chrome()
self.wait = WebDriverWait(self.driver, 10)
self.accepted_cookies = False
self.base_urls = [f"https://hiheapk.com/category/games/page/{i}/" for i in range(1, 0, -1)]
self.base_url = "https://hiheapk.com/category/games/"
self.current_url_index = 0
self.current_url_index = 0
self.image_path = r"C:\Users\Dawid\Desktop\skrypt gamejot\WP\SKRYPTY\DROID.COM - HIHE\img"
self.text_path = r"C:\Users\Dawid\Desktop\skrypt gamejot\WP\SKRYPTY\DROID.COM - HIHE\arty"
self.processed_games_file = r"C:\Users\Dawid\Desktop\skrypt gamejot\WP\SKRYPTY\DROID.COM - HIHE\processed_games.txt"
self.links_file = r"C:\Users\Dawid\Desktop\skrypt gamejot\WP\SKRYPTY\DROID.COM - HIHE\opublikowane linki.txt"
self.processed_games = self.load_processed_games()
def load_processed_games(self):
if os.path.exists(self.processed_games_file):
with open(self.processed_games_file, 'r', encoding='utf-8') as f:
return set(line.strip() for line in f)
return set()
def save_processed_game(self, title):
with open(self.processed_games_file, 'a', encoding='utf-8') as f:
f.write(f"{title}\n")
self.processed_games.add(title)
def handle_cookies(self):
if not self.accepted_cookies:
try:
agree_button = self.wait.until(
EC.element_to_be_clickable((
By.CSS_SELECTOR,
"button.css-1n36tvh"
))
)
agree_button.click()
self.accepted_cookies = True
time.sleep(1)
logger.info("Cookies zaakceptowane")
except Exception as e:
logger.error(f"Błąd przy akceptacji cookies: {str(e)}")
def get_next_game(self):
try:
if self.current_url_index >= len(self.base_urls):
logger.info("Osiągnięto ostatnią stronę")
return None
current_url = self.base_urls[self.current_url_index]
logger.info(f"Sprawdzam stronę {self.current_url_index + 1}: {current_url}")
if self.driver.current_url != current_url:
self.driver.get(current_url)
time.sleep(5)
self.handle_cookies()
games_container = self.wait.until(
EC.presence_of_element_located((By.CSS_SELECTOR, "main#main-site div.app-p"))
)
games = games_container.find_elements(By.CSS_SELECTOR, "div.bav.bav1")
for game in games:
title = game.find_element(By.CSS_SELECTOR, "a").get_attribute("title")
if title not in self.processed_games:
return game
self.current_url_index += 1
return self.get_next_game()
except Exception as e:
logger.error(f"Błąd: {str(e)}")
return None
def get_game_data(self, game_element):
try:
logger.info("=== Rozpoczynam pobieranie danych gry z hiheapk ===")
# Znajdź link do posta
game_url = game_element.find_element(By.CSS_SELECTOR, "a").get_attribute("href")
logger.info(f"URL gry: {game_url}")
# Przejdź do strony gry
self.driver.get(game_url)
time.sleep(3)
logger.info("Przejście na stronę gry")
# Pobierz obraz wyróżniający
featured_image = self.driver.find_element(
By.CSS_SELECTOR,
"div.image-single"
).get_attribute("style")
featured_image = re.search(r'url\((.*?)\)', featured_image).group(1)
featured_image = featured_image.replace('"', '').replace("'", '')
logger.info(f"Znaleziono obrazek główny: {featured_image}")
# Pobierz tytuł
title = self.driver.find_element(By.CSS_SELECTOR, "h1.main-box-title").text
logger.info(f"Tytuł: {title}")
# Pobierz dane szczegółowe
details_elements = self.driver.find_elements(By.CSS_SELECTOR, "div.app-icb.data-app div.da-s")
details = {}
for element in details_elements:
label = element.find_element(By.CSS_SELECTOR, "b").text
if label == "Developer":
details[label] = element.find_element(By.CSS_SELECTOR, "a").text
else:
details[label] = element.text.replace(label, '').strip()
# Pobierz opisy
short_description = self.driver.find_element(By.CSS_SELECTOR, "div.descripcion").text
detailed_description = self.driver.find_element(By.CSS_SELECTOR, "div#descripcion.box").text
# Pobierz screenshoty
screenshots_container = self.driver.find_element(By.CSS_SELECTOR, "div.box.imagenes div.px-carousel-container")
screenshots = screenshots_container.find_elements(By.CSS_SELECTOR, "img")
screenshot_urls = [img.get_attribute("src") for img in screenshots]
# Pobierz obrazek wyróżniający
self.download_and_save_image(featured_image, f"{title} apk download")
# Pobierz screenshoty
for i, screenshot_url in enumerate(screenshot_urls, 1):
self.download_and_save_image(screenshot_url, f"{title}{i}")
# Pobierz kategorie
categories = []
try:
categories_container = self.driver.find_element(By.CSS_SELECTOR, "div.meta-cats ul.post-categories")
category_elements = categories_container.find_elements(By.CSS_SELECTOR, "li a")
categories = [cat.text for cat in category_elements]
logger.info(f"Znaleziono kategorie: {categories}")
except Exception as e:
logger.warning(f"Nie udało się pobrać kategorii: {str(e)}")
# Zapisz opis do pliku
self.save_to_file(title, detailed_description)
return {
'title': title,
'description': detailed_description,
'short_description': short_description,
'developer': details.get('Developer', 'Unknown'),
'tags': categories, # Zmiana z tej linii
'release_date': details.get('Released on', time.strftime("%Y-%m-%d")),
'version': details.get('Version', '1.0.0')
}
except Exception as e:
logger.error(f"Błąd podczas pobierania danych gry: {str(e)}\n{traceback.format_exc()}")
return None
def download_and_save_image(self, url, filename):
try:
filename = filename.replace(':', '')
response = requests.get(url)
if response.status_code == 200:
file_path = os.path.join(self.image_path, f"{filename}.webp")
img = Image.open(BytesIO(response.content))
if "apk download" in filename:
img = img.resize((150, 150))
img.save(file_path, 'WEBP', quality=80)
print(f"Zapisano obraz: {file_path}")
return True
except Exception as e:
print(f"Błąd podczas pobierania obrazu {filename}: {str(e)}")
return False
def save_to_file(self, title, description):
try:
title = title.replace(':', '')
file_path = os.path.join(self.text_path, f"{title}.txt")
# Usuń elementy img i paragrafy ze stylowaniem tekstu na środku
cleaned_text = re.sub(r'' in paragraph:
# Dla nagłówków h2
text = paragraph.replace('
{text}
\n') elif block.startswith('## '): # Nagłówek H2 text = block.replace('## ', '') converted_text.append(f'\n{text}
\n') elif block.startswith('### '): # Nagłówek H3 text = block.replace('### ', '') converted_text.append(f'\n{text}
\n') else: # Zwykły paragraf # Konwersja pogrubienia i kursywy block = re.sub(r'\*\*(.+?)\*\*', r'\1', block) block = re.sub(r'\*(.+?)\*', r'\1', block) converted_text.append(f'\n{block}
\n') # Połącz wszystkie bloki z dodatkowym odstępem return '\n\n'.join(converted_text) def add_article_content(self, title): try: logging.info("Rozpoczynam dodawanie treści artykułu") # Usuń dwukropek z nazwy dla wyszukiwania pliku safe_title = title.replace(':', '') # Odczytaj zawartość pliku AI używając bezpiecznej nazwy ai_file_path = os.path.join(self.articles_path, f"{safe_title} AI.txt") with open(ai_file_path, 'r', encoding='utf-8') as f: original_content = f.read() # Konwertuj zwykły tekst HTML na format bloków WordPress paragraphs = original_content.split('\n') wp_blocks = [] for paragraph in paragraphs: paragraph = paragraph.strip() if not paragraph: continue # Dodaj odpowiednie znaczniki WordPress dla każdego paragrafu if '' in paragraph:
# Dla nagłówków h2
text = paragraph.replace('', '').replace('
', '')
wp_blocks.append(f'\n
{text}
\n') else: # Dla zwykłych paragrafów wp_blocks.append(f'\n{paragraph}
\n') # Połącz wszystkie bloki wp_content = '\n\n'.join(wp_blocks) # Skopiuj zawartość do schowka pyperclip.copy(wp_content) # Znajdź i uzupełnij pole tytułu title_field = self.wait.until( EC.presence_of_element_located(( By.CSS_SELECTOR, "textarea.components-textarea-control__input[placeholder='Add title']" )) ) title_field.clear() title_field.send_keys(title) logging.info("Uzupełniono tytuł") # Znajdź pole edytora treści content_field = self.wait.until( EC.presence_of_element_located((By.ID, "post-content-0")) ) logging.info("Znaleziono pole treści") # Kliknij w pole treści content_field.click() time.sleep(1) # Symuluj Ctrl+A (zaznacz wszystko) actions = ActionChains(self.driver) actions.key_down(Keys.CONTROL).send_keys('a').key_up(Keys.CONTROL) actions.perform() time.sleep(0.5) # Symuluj Ctrl+V (wklej) actions = ActionChains(self.driver) actions.key_down(Keys.CONTROL).send_keys('v').key_up(Keys.CONTROL) actions.perform() time.sleep(1) # Upewnij się, że WordPress zauważył zmianę self.driver.execute_script(""" arguments[0].dispatchEvent(new Event('input', { bubbles: true })); arguments[0].dispatchEvent(new Event('change', { bubbles: true })); """, content_field) logging.info("Uzupełniono treść artykułu") time.sleep(2) except Exception as e: logging.error(f"Błąd podczas dodawania treści artykułu: {str(e)}") def add_tags(self, tags): try: logger.info("Rozpoczynanie dodawania kategorii") time.sleep(3) # Kliknij przycisk "Add New Category" tylko raz na początku initial_add_button = self.wait.until( EC.element_to_be_clickable(( By.CSS_SELECTOR, "button.editor-post-taxonomies__hierarchical-terms-add.is-link" )) ) initial_add_button.click() time.sleep(1) # Teraz dodajemy wszystkie kategorie w pętli for tag in tags: try: logger.info(f"Próba dodania kategorii: {tag}") # Znajdź pole input po ID i wpisz kategorię input_field = self.wait.until( EC.presence_of_element_located((By.CSS_SELECTOR, "input#inspector-text-control-0")) ) input_field.clear() input_field.send_keys(tag) time.sleep(1) # Kliknij przycisk submit aby dodać kategorię submit_button = self.wait.until( EC.element_to_be_clickable(( By.CSS_SELECTOR, "button.editor-post-taxonomies__hierarchical-terms-submit.is-secondary" )) ) submit_button.click() logger.info(f"Dodano kategorię: {tag}") time.sleep(2) # Czekaj między dodawaniem kategorii except Exception as e: logger.error(f"Błąd podczas dodawania kategorii {tag}: {str(e)}") continue except Exception as e: logger.error(f"Błąd podczas dodawania kategorii: {str(e)}") def cleanup(self): try: logger.info("Zamykanie przeglądarki") if self.driver: self.driver.quit() except Exception as e: logger.error(f"Błąd podczas zamykania przeglądarki: {str(e)}") def main(): techloky = TechlokyScraper() wp = WordPressAutomation(article_title="") text_modifier = TextModifier() posts_counter = 0 # Initialize counter MAX_POSTS = 5 # Set maximum posts limit try: while True: # Outer loop for multiple sessions if wp.login(): processed_games_file = r"C:\Users\Dawid\Desktop\skrypt gamejot\WP\SKRYPTY\DROID.COM - HIHE\processed_games.txt" links_file = r"C:\Users\Dawid\Desktop\skrypt gamejot\WP\SKRYPTY\DROID.COM - HIHE\opublikowane linki.txt" logger.info("Login successful") while posts_counter < MAX_POSTS: # Inner loop for post creation game_element = techloky.get_next_game() if game_element: data = techloky.get_game_data(game_element) if data: title = data['title'] logger.info(f"Got data for game: {title}") safe_title = title.replace(':', '') input_file_path = os.path.join(wp.articles_path, f"{safe_title}.txt") output_file_path = os.path.join(wp.articles_path, f"{safe_title} AI.txt") text_modifier.modify_text(input_file_path, output_file_path, title) wp.article_title = title wp.developer = data['developer'] wp.short_description = data['short_description'] wp.tags = data['tags'] wp.release_date = data['release_date'] wp.version = data['version'] wp.process_single_article() techloky.save_processed_game(title) posts_counter += 1 # Increment counter after successful post logger.info(f"Saved processed game: {title} (Post {posts_counter}/{MAX_POSTS})") time.sleep(5) else: logger.error("Failed to get game data") else: logger.info("No more games found") break # After reaching post limit or no more games logger.info(f"Reached {posts_counter} posts. Press Enter to continue with next batch or 'q' to quit...") user_input = input() if user_input.lower() == 'q': logger.info("User chose to quit") break else: posts_counter = 0 # Reset counter for next batch techloky = TechlokyScraper() # Reinitialize scrapers wp = WordPressAutomation(article_title="") continue else: logger.error("WordPress login failed") break except Exception as e: logger.error(f"Error in main program loop: {str(e)}") finally: logger.info("Cleaning up...") techloky.cleanup() wp.cleanup() logger.info("Program finished") input("Press Enter to exit...") if __name__ == "__main__": main()Game information
| Name | Girl Alone |
| Developer | fleximindg |
| Category | Apps, Games, Strategy |
| Version | 1.2.15 |
| Size | 21.7GB |
| Updated | 2025-03-08 |
| Platform | Android |
Advertisement
You may also like






More Strategy games
- Doodle Empires
- Norland Mobile
- Manor Lords Mobile
- Cardfight!! Vanguard Dear Days 2
- Sid Meier's Civilization VII
- PVZ Fusion Niejo
- Pvz Hybrid
- PvZ Reborn
- Slay the Spire 2
- PVZ GRAFTED
- Frostpunk 2 Mobile
- Nulls Brawl
- Age of History 3
- 多元守卫者 Diverse Defenders
- Tank Company
- Arabian Hero